
Introduction to Mongo Database

It's been long time, since the last post. Let's get to know about mongo database. So mongo is one of the front runners in nosql databases. Nosql databases do not adhere to rules and principles to standard relational databases. So coming to Mongo it a document oriented database which is written in C++.
 
Mongo is an open source database. It is simple to install more of a plug and play type.
 
Once you are done with the mongo installation To start the mongo server in our local machine. Execute the command in command terminal
 
C:\MongoDB\bin\mongod.exe --config="C:\MongoDB\mongo.config"
 
To start the client in our local machine execute the following command in the command terminal
 
C:\MongoDB\bin\mongo
 
Upon executing we can see the following screen
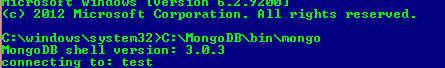


 By default there will be a test database created in our mongo database. So it will be connected to that particular database.
 
We can create our own database by executing the following command
 
 use local_test
 
So a database under name local_test will be created. To see the list of databases created we can use the following command
 
show dbs   But upon executing the following command you will not see the database which is created just now local_test.


This is because it is an empty database. We need to insert a document to make it visible.
 
In mongo data can be inserted only in Json format.

To insert the data execute the following command
 
db.firstdocument.insert({"Name":"AAA","ID":"101"})
 
Now if we execute show dbs we can see the local_test database being created.
 
When we inserted firstdocument in local_test, automatically a collection is created under that name.So basically documents are stored in collection. We can insert any number of rows(i.e. documents) in a given collections
 
To display total number of collections in a given database
 
show collections
 
 
system.indexes  is implicitly created upon creating a collection. This stores indexes information of all documents
 
To see data inside the collections
 
db.firstdocument.show()


_id is a unique value which is automatically generated while inserting a row. we can override _id
value and pass our own value in the following way


These are some of the basics queries in mongo in the next article we will see how to update,delete operations on databases and collections
 
Hope this article helps you in understanding basic mongo queries

Comments

Post a Comment

Popular posts from this blog

Comparing Objects in Informatica

We might face a scenario where there may be difference between PRODUCTION v/s SIT version of code or any environment or between different folders in same environment. In here we go for comparison of objects we can compare between mappings,sessions,workflows In Designer it would be present under "Mappings" tab we can find "Compare" option. In workflow manger under "Tasks & Workfows" tab we can find "Compare" option for tasks and workflows comparison respectively. However the easiest and probably the best practice would be by doing using Repository Manager.In Repository Manager under "Edit" tab we can find "Compare" option. The advantage of using Repository manager it compares all the objects at one go i.e. workflow,session and mapping. Hence reducing the effort of individually checking the mapping and session separately. Once we select the folder and corresponding workflow we Can click compare for checking out ...

Labelling and creating queries in informatica

Informatica components i.e. mappings,session,workflows,transformation are moved from one environment to another environment say from development to SIT can be done in various ways such as --Export the xml's and again import the xml's in the respective environment --Drag and Drop objects from one repository to another repository For the above process to be done you should have required access across environments. One other way is labelling the components and then creating queries in repository manager. Using these queries components are moved across environment's We need to go to the repository manager and select the version tab and select label Then click new label and give a name say "Wf Migration" and click OK. There we  have permissions tab where we can give access to other users to use the same label. Now we need to select the workflow which needs to be promoted to higher environment.  Right click on workflow and select "view dependencies...

Pre and Post Sql,Session properties at session level

Sometimes we may have a requirement where might need to drop indexes/truncate table and then load the data. So in here what we can we do is we can go for pre sql in session properties and there we can write the required the sql statements such as dropping indexes or truncating table and after the loads i.e. session gets completed we can recreate the indexes in post sql command. In mapping also we can do the same but it is advisable to do at session level. We even have option in session such as Presession, Postsession command and Postsession failure command. In session go to components tab to find out these options. Upon requirement we can use the following command to run unix scripts for specific purpose. We have email option option for on success/failure scenarios too. Hope this article helps you in understanding post/pre session commands